
LIVE AT ARCO.CAREERS · BUILT SOLO WITH AI
One designer. No engineering team. A live product.
Arco is an AI job-search platform — a scored feed, a coach, and a pipeline, live at arco.careers. It's also a working demonstration of how I design now: every feature specified as a structured prompt, executed through Claude Code, and verified by me on the live deploy.
This case study documents the method as much as the product — including where it broke.
Honest scores over flattering ones
A fit score only works if users can trust a low one.
Coach, don't generate
Tailoring that starts from your real experience, not a template.
The pipeline is the product
From first match to offer in one place — feed, prep, and tracking connected.
Built with the tools it runs on
Designed and shipped solo with Claude Code and Figma MCP.
THE PRODUCT
The evidence, briefly
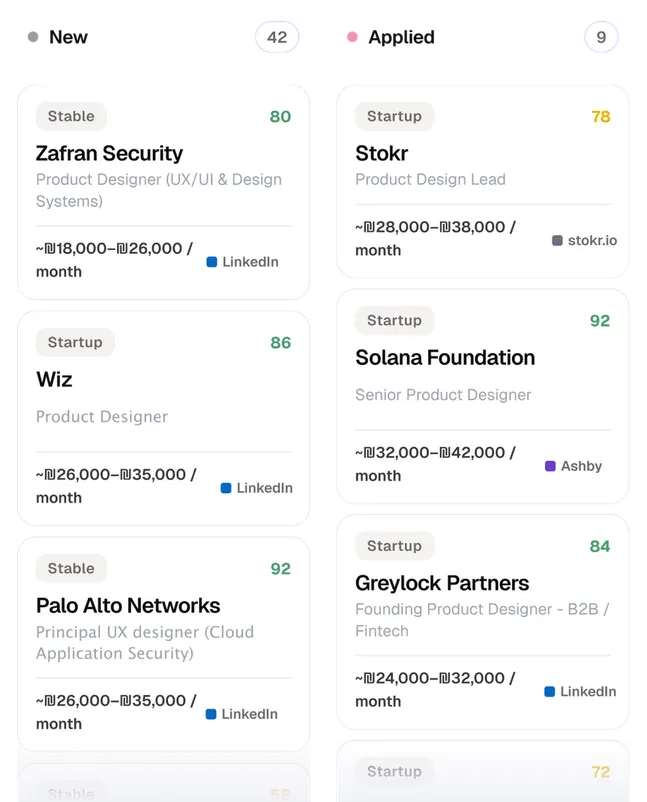
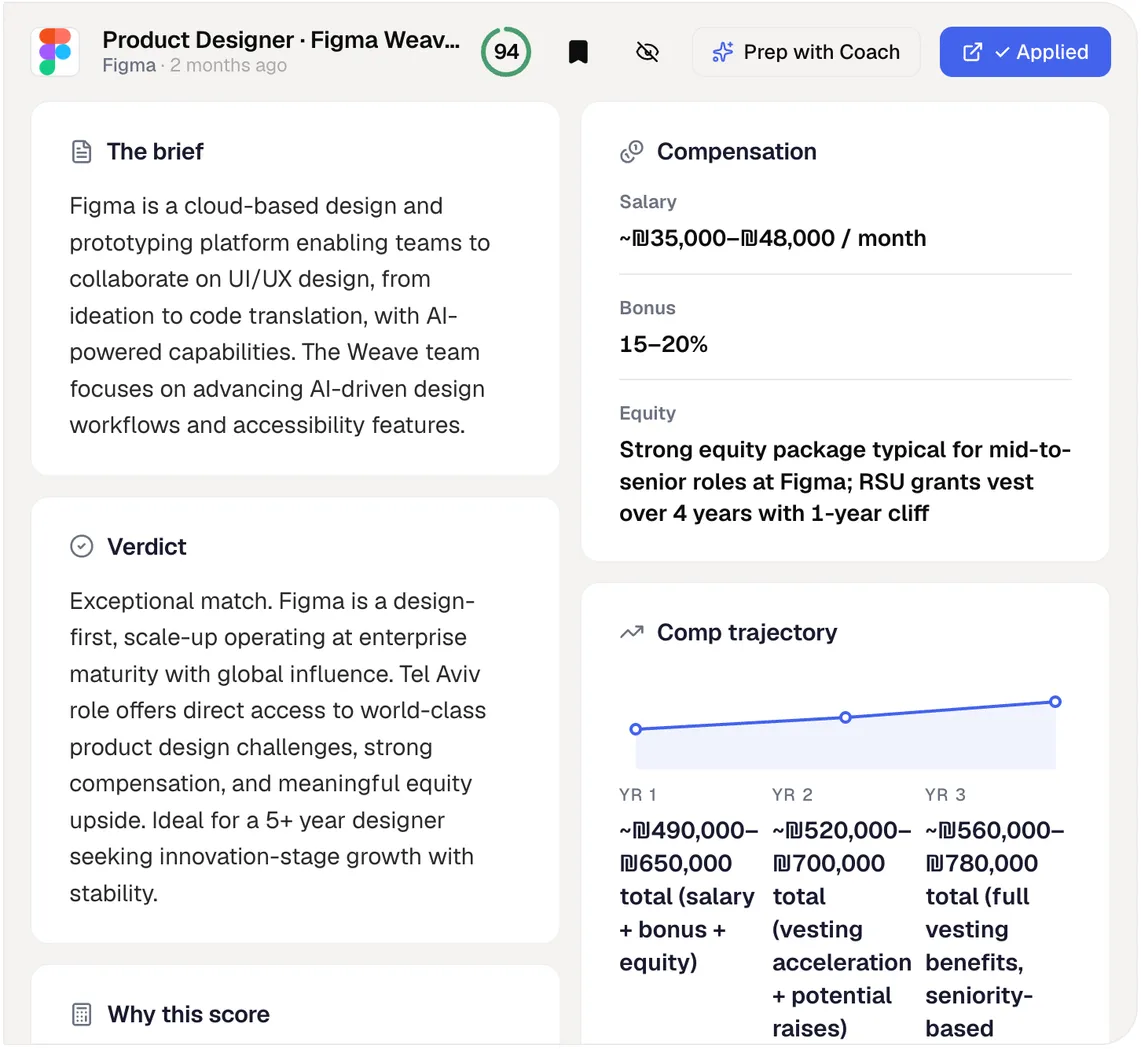
Job boards give you volume and no comprehension. Arco scores every role against your actual profile, explains the score instead of asserting it, and takes you from "who is this company?" to a tailored application — feed, coach, and pipeline in one place. I built it during my own senior-design-role search, which means every scoring decision got tested on the most demanding user available: me, with something at stake.
HOW EVERY FEATURE SHIPS
The loop
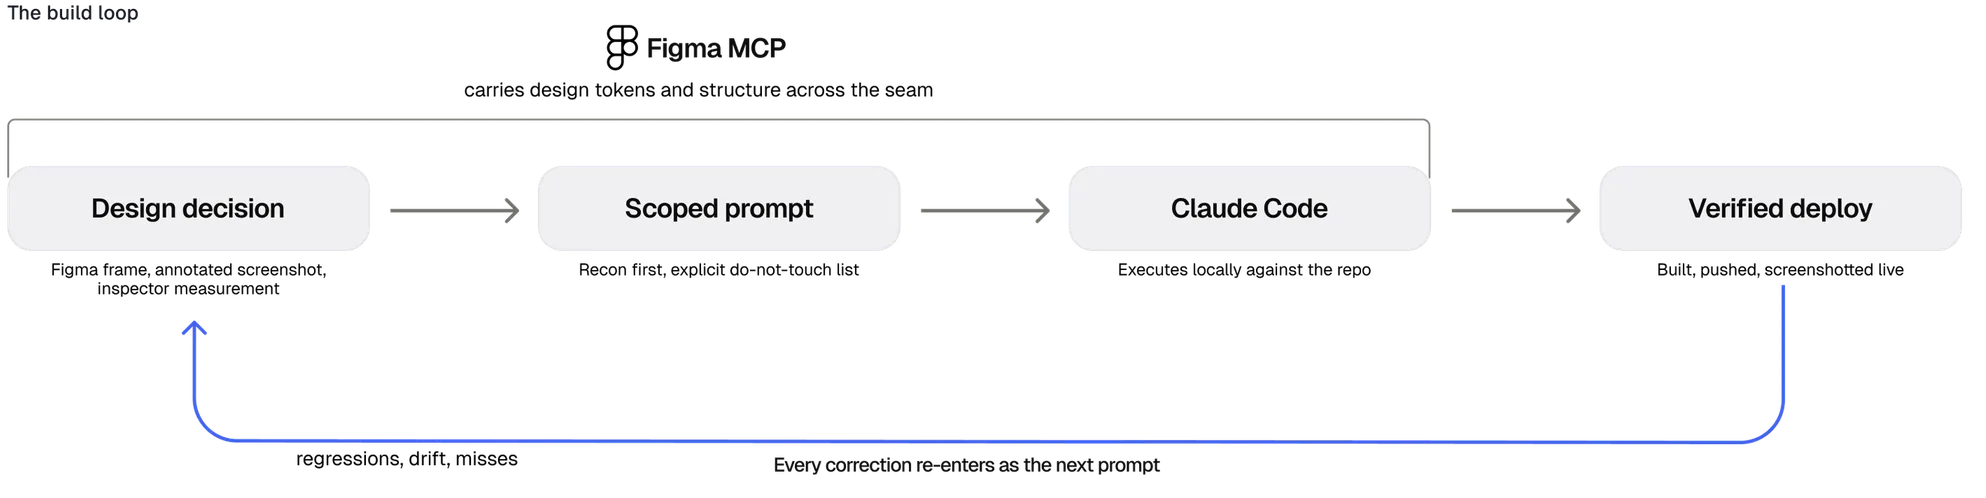
Every feature crosses the same cycle: a design decision, written as a scoped prompt; Claude Code executes it; I verify it on the live deploy. The loop ends at verification, not shipping — most AI-workflow diagrams end at "deploy," and that's the flattering version. What actually travels back around the arrow is regressions, drift, and misses.
A prompt in this system is a design artifact. It opens with reconnaissance — read the code before touching it. It scopes the change surgically. It names what must not be touched. And it closes with a deploy sequence that ends in me checking the live build hash, because "done" is a claim, not a fact.
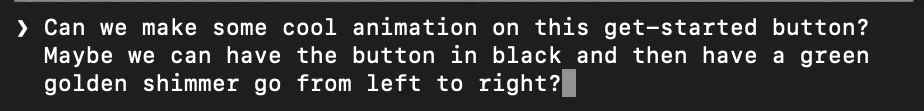
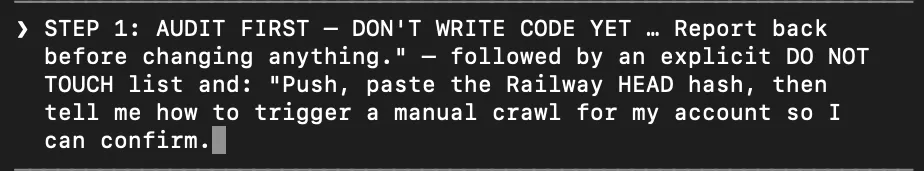
Three months apart. Every line of the second prompt was paid for by a specific incident.
THE JUDGMENT BOUNDARY
What the AI couldn't decide
The honest question about AI-built products is: what did the human actually do? The answer is everywhere the model needed a decision it had no basis to make — and everywhere it was wrong and didn't know it.
"If the user wants to start clicking around the screen, at least the banner is still there."
Claude specced a full-screen waiting takeover for the first crawl. I killed it. A takeover hijacks the app for minutes and strips the user of agency. The plan was rewritten around enhancing the banner in place — a call about user agency, not code.
"Not sure 72 is good enough? How come?"
The optimizer took my resume-match score from 62 to 72 and I pushed back. The system's answer held: the missing points were substance gaps it refused to pretend away. A tool that returned 95 would be lying, and lying resumes get found out in interviews. I kept the 72. That exchange became the product's core principle: the score's job is to be right, not to be liked.
"Fix this, it's the 4th time now lol"
A modal button kept coming back broken after each "fix." On the fourth attempt the model finally admitted it had been adjusting the wrong attribute the whole time. The loop breaks on human persistence, not model confidence. That's what supervision of AI work actually looks like.
None of these live in the code. They live in the taste, the pushback, and the refusal to accept a confident wrong answer — which is the job.
WHERE IT BROKE
Paid for in incidents
Every rule in my prompt structure exists because its absence cost me something. The method wasn't designed; it accreted.
The dist trap. The deploy pipeline serves a pre-built frontend from git. For weeks, the AI would edit source, commit, push — and the live product wouldn't change, because the build step was silently skipped. It took multiple "deployed but unchanged" incidents before the fix stopped being a reminder and became infrastructure: a pre-commit hook that mechanically blocks the failure, because rules the AI has to remember are rules it will eventually forget.
THE RULE — EVERY PROMPT ENDS WITH BUILD, STAGE DIST, PUSH, VERIFY THE LIVE HASH.
The migration that crashed three times. One database migration crashed production three times in a row — type mismatches the local test environment couldn't reproduce, then orphaned rows from deleted users. Each crash rolled back cleanly; the cost was downtime, not corruption. The doctrine that came out of it: read the real schema before writing a migration, assume dirty legacy data, and dry-run every migration against production inside a rollback before pushing. An engineer might have known this on day one. I bought it with three crashes.
THE RULE — READ THE REAL SCHEMA FIRST. DRY-RUN EVERY MIGRATION AGAINST PRODUCTION INSIDE A ROLLBACK.
The failures nothing catches. The worst class of failure throws no error. A one-word bug silently reported zero new jobs on every digest run. A hard-coded timeout was quietly cutting off the majority of scraping runs. Both shipped, both ran, and nothing in the loop caught them — until a number looked wrong to me ("2 jobs in total for global remote blockchain designer jobs is a bit low?") and a read-only audit traced it down. Verification is strong on what you can see. On what you can't, the last line of defense is a human who knows what the numbers should feel like.
THE RULE — WHEN A NUMBER FEELS WRONG, RUN A READ-ONLY AUDIT BEFORE ASSUMING IT'S FINE.
These rules now live in the repo itself — a CLAUDE.md the AI reads before working, and hooks that enforce what memory can't. The method's output isn't just the product; it's the guardrails.
AI-NATIVE BY DESIGN
Designed with AI, for AI
Every score costs money, and where the spending stops is a design decision. A full crawl pulls 250–350 raw roles; a location gate cuts that to roughly 115. Scoring all of them for every free user was unsustainable — so free crawls run a cheap heuristic pre-rank first and send only the top 50 candidates to the model, while paying users get every candidate scored. Everyday tasks route to a lighter model; judgment-heavy work — merging four CVs and resolving their contradictions — gets the stronger one. Where those seams sit is revisited constantly. The paywall stays honest by the same logic: the locked matches are real ranked results, not filler.
The same job once showed a 92 on the board and a 62 in the optimizer. Both were correct: one measured job fit, the other how well my resume made the case. The fix wasn't reconciling the numbers — it was naming them. "Job fit" and "Resume match" are now two labeled scores, and the gap between them is the pitch: a great-fit job your resume undersells is exactly what the coach exists for. Honesty is enforced in small places too. The first-crawl banner used to cycle fake timer-driven progress phases; it now reports real pipeline stages, and its time estimate was corrected against observed run data — "usually 5–10 minutes," because that's what's true. A "NEW" badge that mislabeled old jobs was a lie in miniature, and got the same treatment.
That includes designing for AI, not just with it: model selection, cost seams, prompt architecture, and the UX of machine judgment (how a score earns trust, how a coach corrects without condescending) are product design decisions here, as much as any screen.
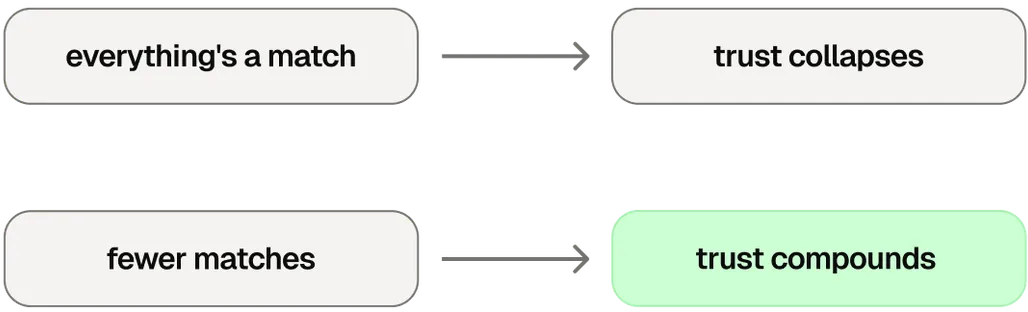
A score that flatters everyone is a score nobody checks twice. Fewer, harder matches are what make the number worth reading.
THE COACH
A different kind of space
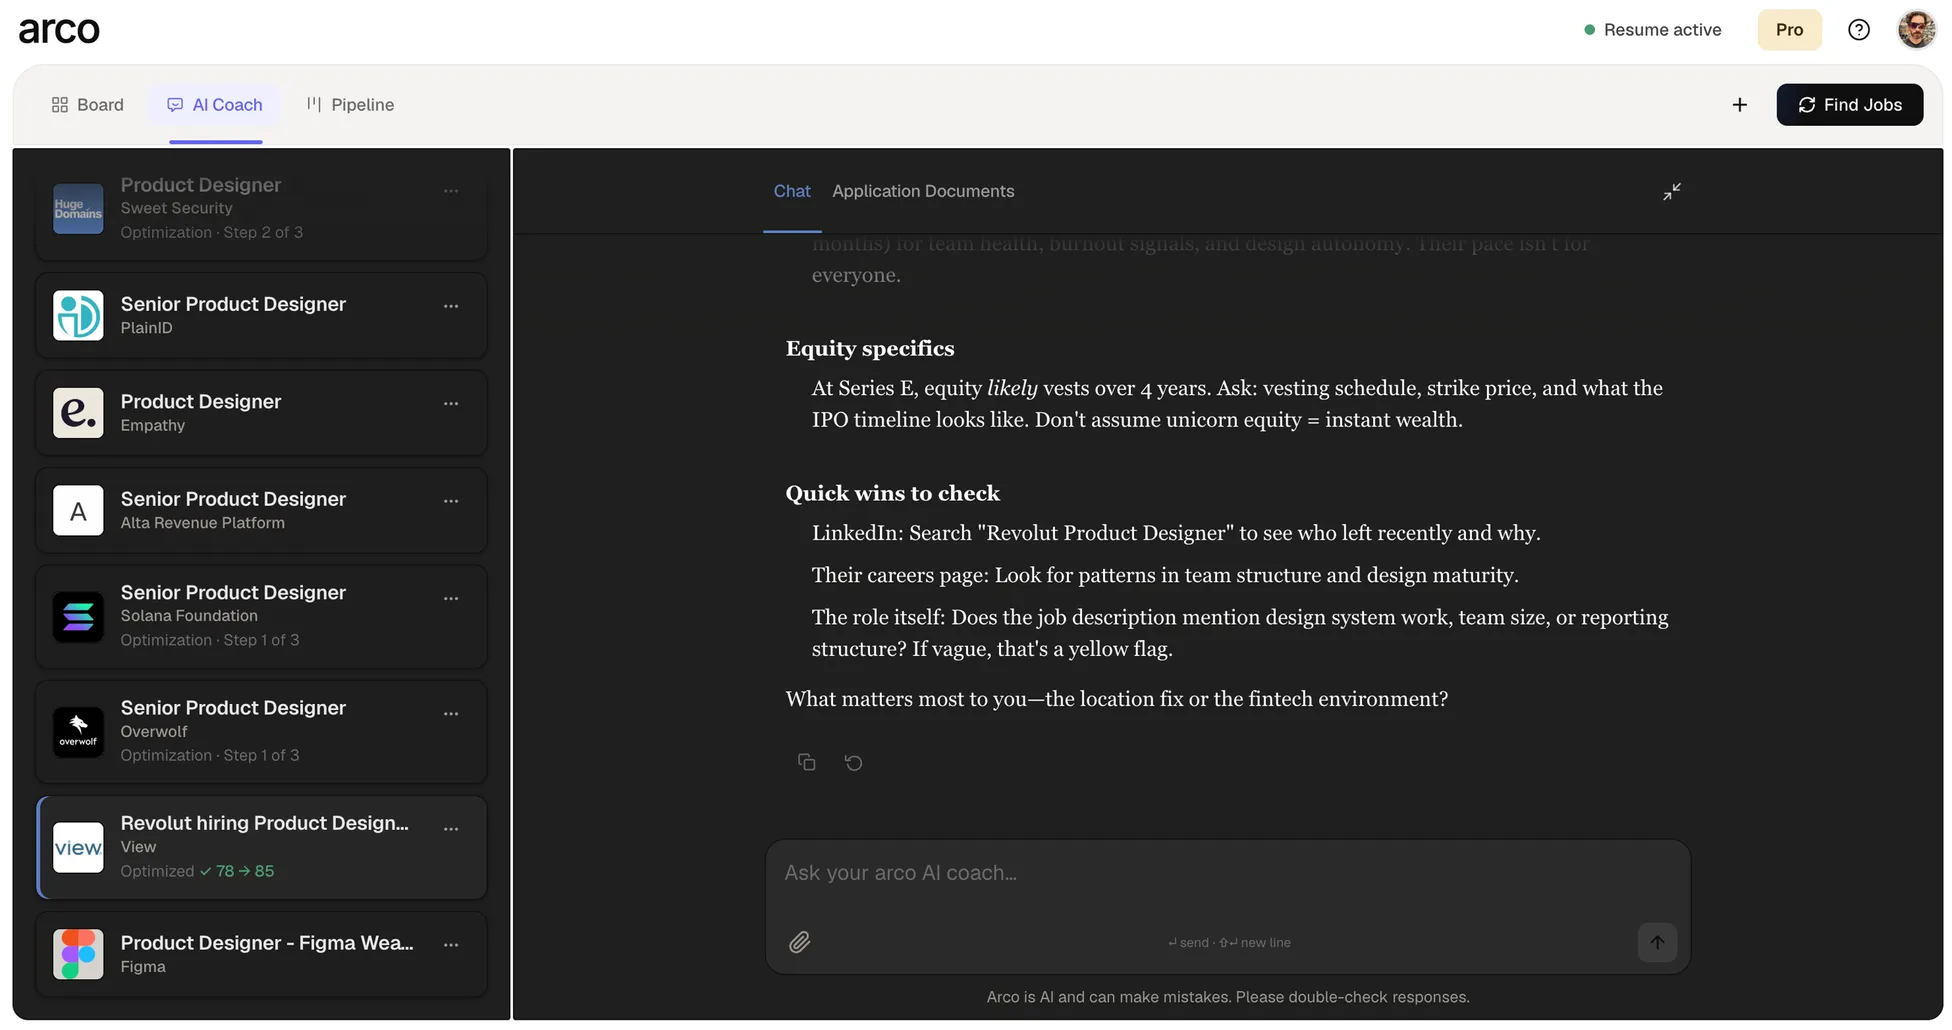
The coach began as one tab inside a dense, multi-panel product — reading as "more app," not a conversation. Three treatments were mocked up: a quiet inset canvas (separation without identity), a slate-blue tint on the light surface, and a fully dark immersive coach that first got filed as "a big bet — maybe later." Two observations reframed it: the board's rail was already dark, making dark the consistency fix rather than the risk; and the treatment had to survive the panel expanding into a full-width workspace, which meant both ends of that animation needed the same surface.
The typography carries the same intent: the app runs on Geist, but the AI's messages are set in Georgia — a serif voice for the machine, so you always know who's talking. Tailoring is tracked per job — 78 → 85 — without ever touching your master CV: the machine's judgment is scoped, and the microcopy promises it.
OUTSIDE FORCES
The system doesn't control its world
Job sourcing is fragile by nature. Boards block crawlers, change structure without notice, or re-render as apps with nothing to parse. Two blockchain sources were decommissioned in a single June week — one behind a new bot wall, one rebuilt as a JavaScript app with no static feed — and the survivor is read through its sitemap instead of its pages, because that's the surface that doesn't break. A clean, deduplicated, correctly classified feed is continuous maintenance, not a one-time integration.
The strangest design constraint came from payments. A merchant-of-record's category review read Arco as a "resume builder" and a "job board" — two categories it wouldn't support — and declined checkouts. Both readings were wrong, but they were plausible from the outside, and that was the design problem: the product's surface was underselling its actual center. The fix was positioning, executed like any other feature: landing copy rewritten to lead with the AI matching and coaching layer, CV optimization demoted to a supporting beat, and a one-line counter-framing that now defines the product externally — Arco doesn't sell job listings, host a public board, or sell CV templates; the subscription is the intelligence layer. A payment processor forced the sharpest positioning work of the project.
LIMITS
What this method can't do
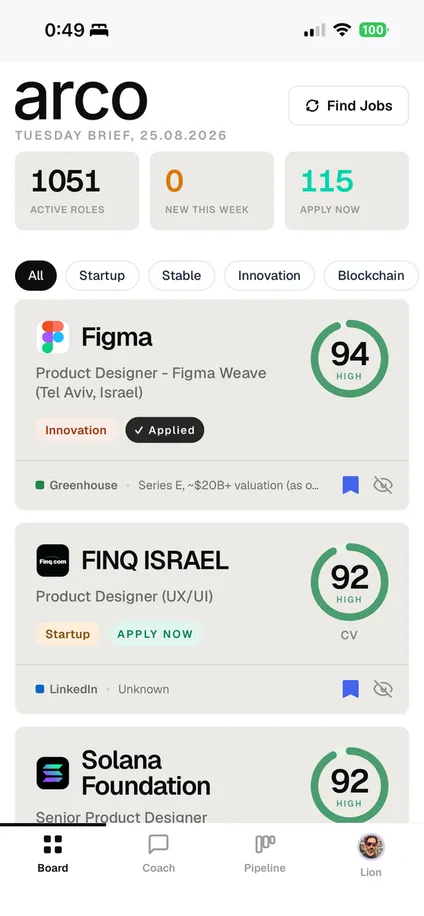
The honest version: this way of working has real edges. Failures that throw no error persist until a human notices output looks wrong. A confident model can iterate on the wrong attribute four times in a row. Production taught me database lessons an engineer would have known on day one. And the first surface you build is rarely the one you keep — Arco started mobile-first under another name; the desktop app overtook it, and mobile is now being rebuilt to match the product it became. That's the honest cost of learning in public.
No usage metrics on this page. Nothing is measured rigorously enough yet to put a number on, and I'd rather show real work than dress it up.
WHERE THIS STANDS NOW
Built, open, next
Working today:
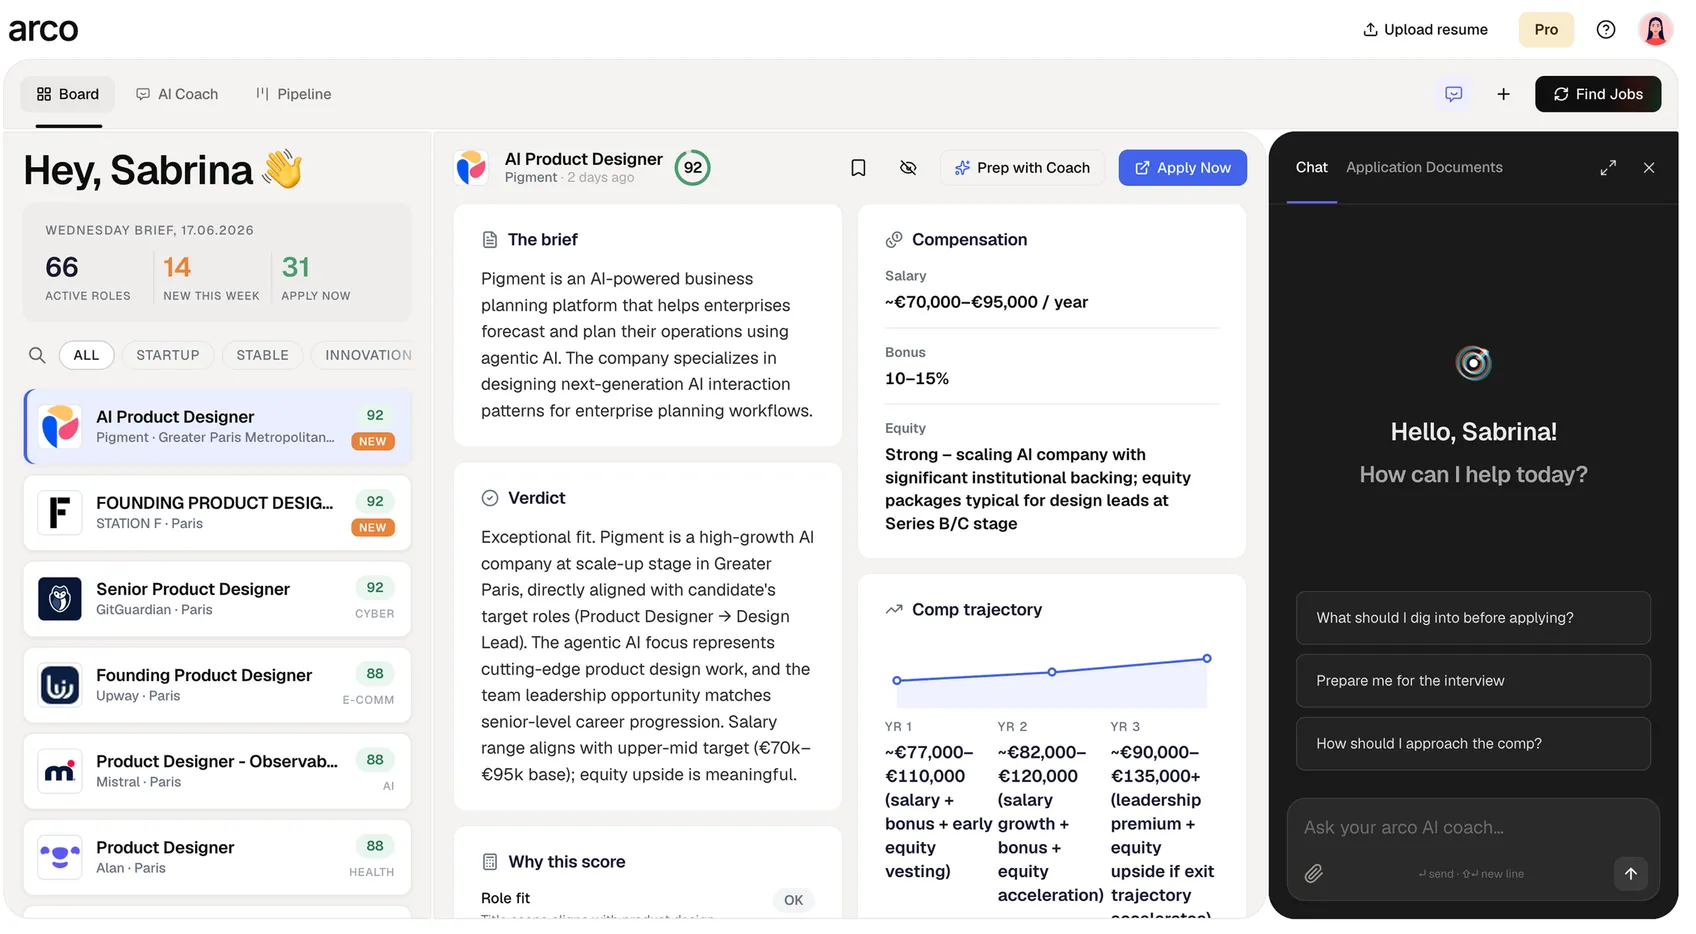
Arco is live at arco.careers. The scored feed, the coach — CV analysis, per-job tailoring, guided optimization — and the pipeline board run end-to-end, with free and Pro tiers defined and a public help center.
Still open:
Payments are in final activation with a merchant of record, so subscriptions aren't switched on yet. The mobile app is being rebuilt to catch up with desktop. Job sources are expanding lane by lane.
Next:
Payments live, mobile redone, sourcing broadened — in that order.
View ProductI design systems, not just screens—products that stay clear under real-world use.